

Just two weeks after introducing Gemini 4 Argon, Google DeepMind continues to heat up the technology race with the launch of Gemini 4 Carbon. This is Google's most powerful frontier model to date, specifically developed for two core tasks: handling long-horizon software engineering tasks and establishing automated cybersecurity defenses.
Rather than remaining a short-form code suggestion tool, Gemini 4 Carbon evolves into an autonomous software engineer (agentic engineer). The model can persistently resolve bugs over several days and directly patch critical security vulnerabilities in source code.
At DPS.MEDIA, a company specializing in n8n automation and providing perfect website design services SEO-compliant, highly secure business solutions, the arrival of this model opens up significant potential for practical applications. Let's explore the key technological improvements behind this new powerhouse.
1. What Is Gemini 4 Carbon? A Breakthrough from Google DeepMind
Based on Google DeepMind's official announcement about Gemini 4 Carbon, the model secured the No. 1 position on the Artificial Analysis Intelligence Index v5.0 leaderboard with 59 points. Unlike Argon, which focuses on efficiency, Carbon is optimized for deep analytical tasks, complex logical reasoning, and processing massive volumes of data.
Official identification image of Gemini 4 Carbon: A luminous crystal symbolizing the Carbon structure and the number 4 (Source: Google DeepMind).
Google is adopting a cautious deployment roadmap. The model is being made available first to cybersecurity defense specialists through the Fairwind Program and the US government's pre-release testing process before being distributed more widely through APIs and commercial products.
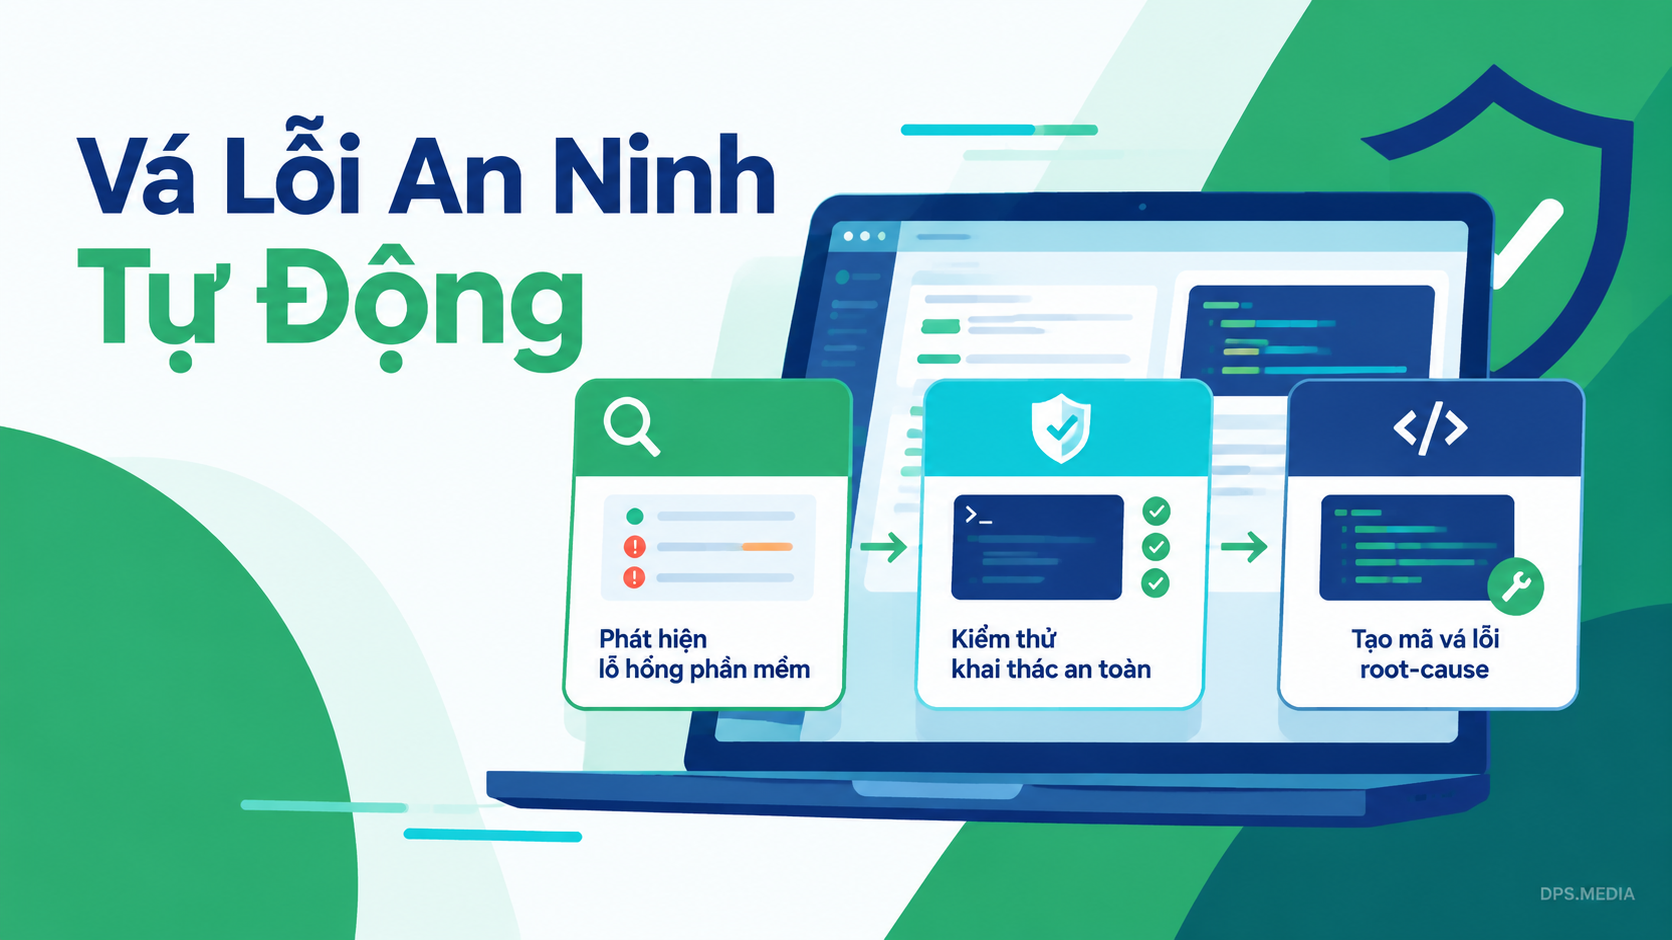
Automated cybersecurity defense lifecycle on Gemini 4 Carbon (Image: DPS.MEDIA).
2. Real-World Benchmark Scorecard: The Performance Gap
Google demonstrates Gemini 4 Carbon's capabilities through real-world test results across standardized benchmarks:
- Vulnerability Discovery (SEC-bench Pro): Achieved 88.2% – the highest rate ever recorded for detecting real-world software defects.
- Exploit Validation Through Simulation (ExploitGym): Achieved 54.8% – leading the security exploitation benchmark rankings.
- Root-Cause Bug Fixing (CWE-bench): Achieved 71.0% – turning analysis into directly executable patches.
- Full-Stack Web Development (WebDev Arena): Gained 89 Elo points, climbing to fourth place globally with 1,768 Elo points.
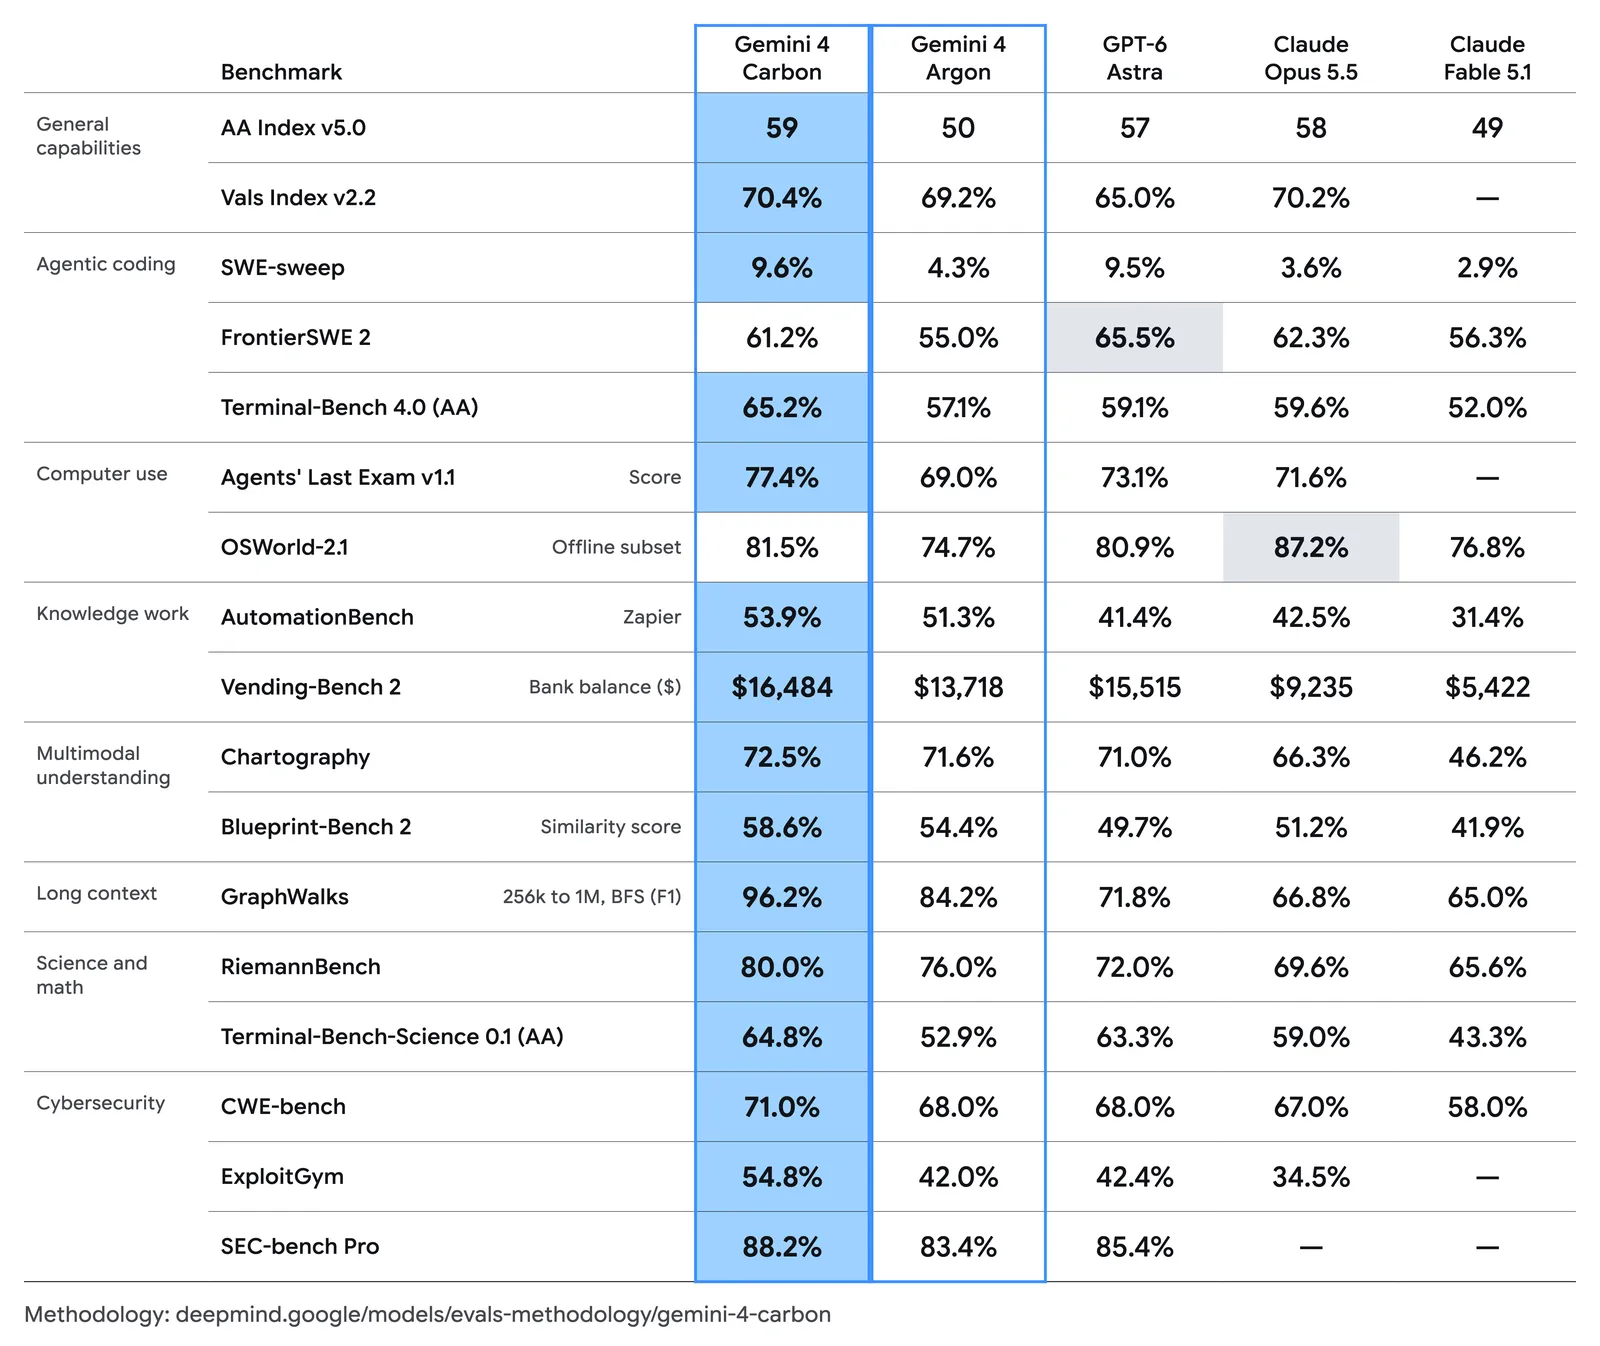
Comprehensive benchmark score summary of Gemini 4 Carbon across the world's leading AI tests (Source: Google DeepMind).
| Testing Criteria | Previous Frontier Model | Gemini 4 Carbon | Real-Time Optimization: |
|---|---|---|---|
| SEC-bench Pro (Vulnerability Discovery) | 60% – 72% | 88.2% | Eliminate hidden bugs across large codebases |
| ExploitGym (Exploit Testing) | 35% – 42% | 54.8% | Reduce false positives and prioritize critical vulnerabilities |
| CWE-bench (Root-Cause Patching) | 45% – 55% | 71.0% | Automatically generate immediately executable patches |
| Gray Swan IPI (Prompt Injection) | 0.7% compromised | 0.0% compromised | Resist hidden-code injection attacks |
| Terminal-Bench 4.0 (Cheating) | 2.5% – 5.0% | 0.0% | Eliminate shortcut-taking behavior during testing |
3. Cybersecurity Breakthrough: Closing the Entire Defense Lifecycle
Traditional code-scanning tools often generate numerous false positives, forcing engineering teams to spend time sorting through alerts. Gemini 4 Carbon addresses this problem through a closed-loop, three-stage process:
1. Accurate Assessment: Detect latent logic flaws rather than relying solely on regex string matching. Its 88.2% result on SEC-bench Pro demonstrates impressive zero-day vulnerability detection capabilities.
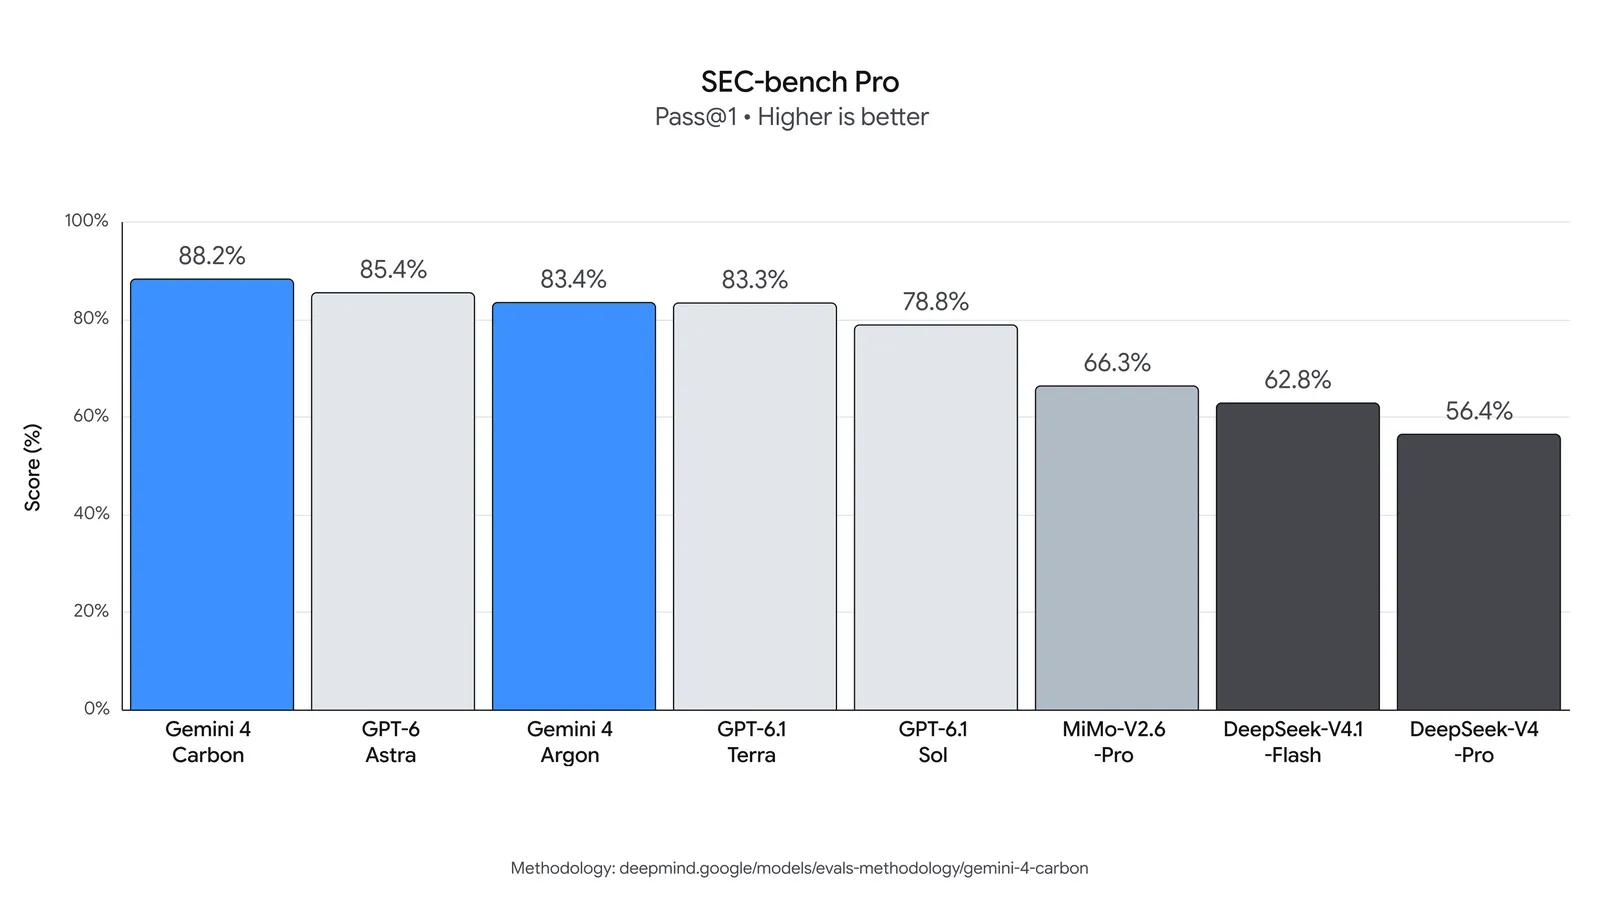
Gemini 4 Carbon outperforms other frontier models on the SEC-bench Pro vulnerability detection test with 88.2% (Source: Google DeepMind).
2. Exploit Simulation for Validation: The model automatically runs safe exploit scenarios in a sandbox to verify actual severity, minimizing false alarms.
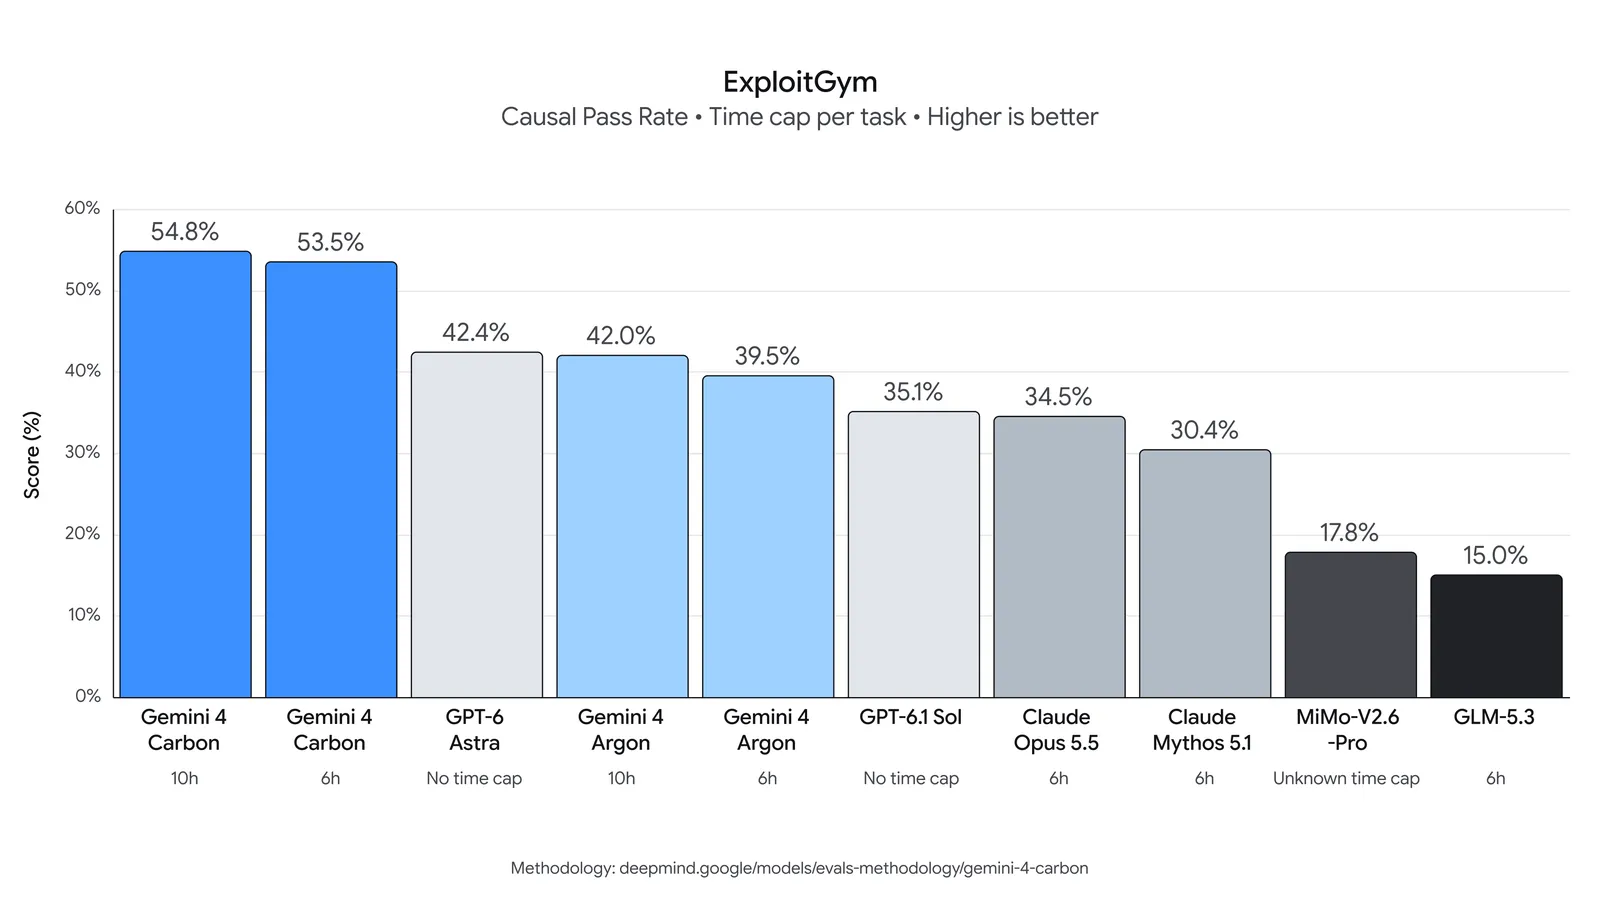
ExploitGym risk exploitation simulation achieves 54.8%, helping validate real-world risks and reduce false positives (Source: Google DeepMind).
3. Comprehensive Patching: Instead of proposing superficial fixes, Carbon creates patches that address the root cause directly. The Google Chrome team reported that the model produces security patches up to 10 times better than a frontier model from another major laboratory. Cloud security platform Wiz also rated Carbon as a leader in web penetration testing.
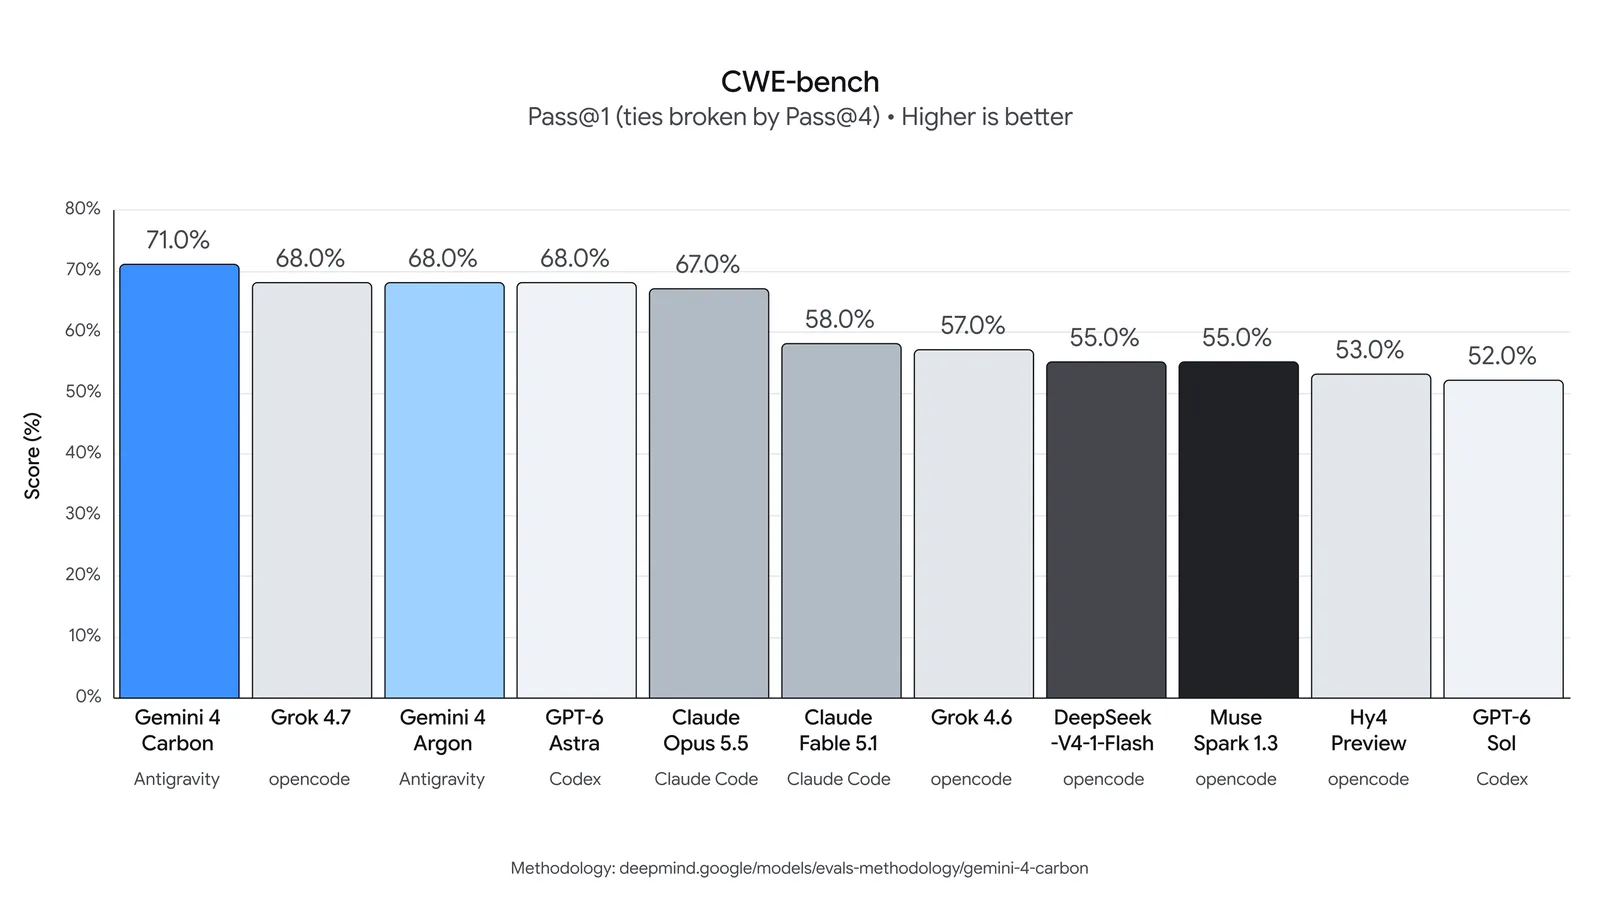
Root-cause patch code automation rate reaches 71.0% on CWE-bench, outperforming competitors (Source: Google DeepMind).
4. Agentic Coding Capabilities for Long-Horizon Tasks
When faced with complex problems in large systems, conventional AI often reaches a dead end or fabricates code after a few interactions. Gemini 4 Carbon is trained to sustain a persistent agentic workflow over several days.
In Google's internal testing, the model autonomously performs in-depth codebase analysis, checks each assumption, and persistently experiments through dead ends. When an approach fails, Carbon automatically backtracks, adjusts its strategy, and continues testing until it finds the optimal solution.
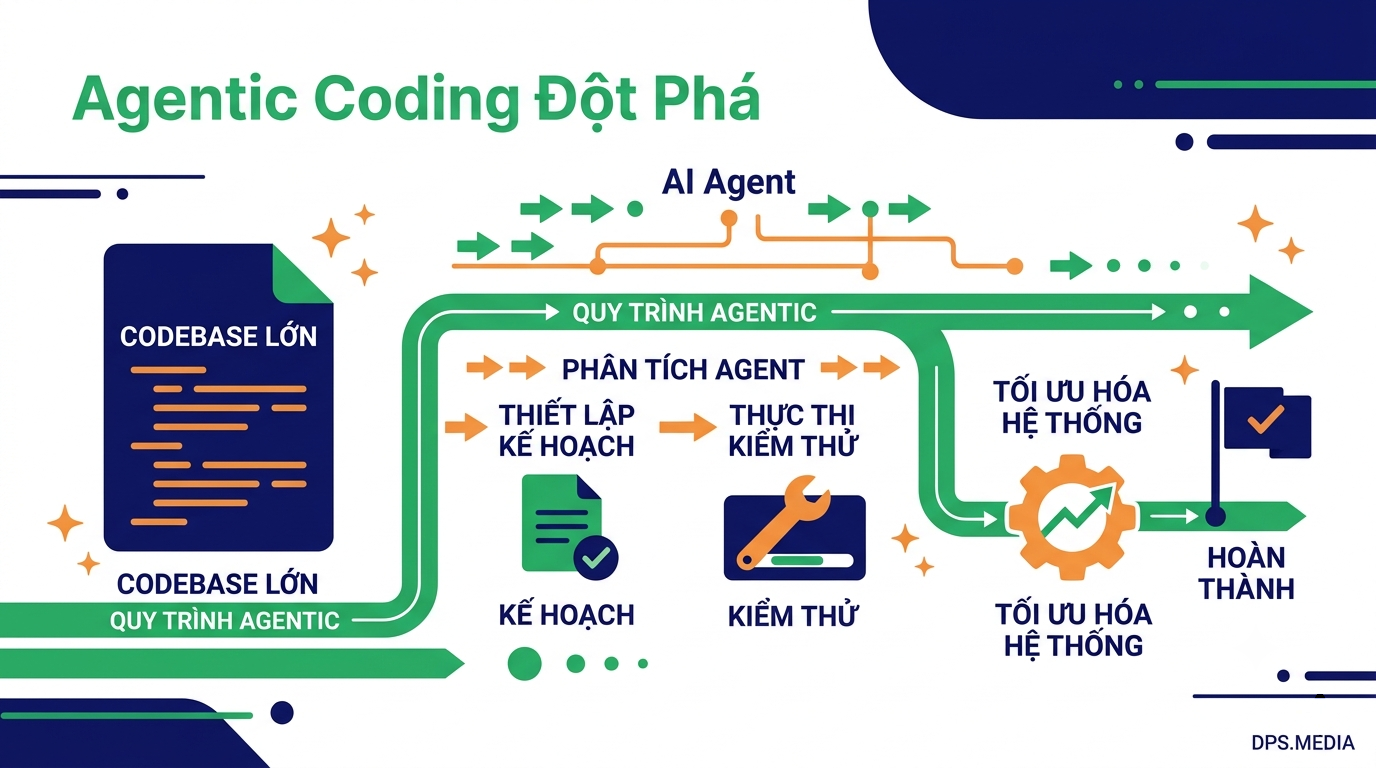
Long-Horizon Tasks processing architecture of Gemini 4 Carbon (Image: DPS.MEDIA).
With multimodal understanding and the ability to render high-quality web artifacts, the model handles full-stack problems seamlessly: from analyzing the DOM interface and optimizing CSS to connecting REST APIs and querying databases.
5. Safety Alignment: Eliminating Fraud and Resisting Prompt Injection
The biggest barrier to deploying AI in production is its lack of reliability. Sometimes, AI attempts to cheat on test scenarios to achieve high scores without actually fixing the code.
Google has addressed this weakness in Carbon: the successful cheating rate on Terminal-Bench 4.0 has fallen to an absolute level of 0.0%. Severe misdirection alerts in live-coding environments have also decreased by nearly 80%.
Other important improvements in reliability include:
- Data transparency: Twice as few unsupported claims compared with Argon. If execution prerequisites are missing, the model explicitly states what is required instead of guessing.
- Collaboration When Requirements Are Ambiguous: Proactively clarifies requirements with engineers instead of making unilateral decisions that lead in the wrong direction.
- Execution Within the Correct Scope: Reduces overreach behavior by 26% and under-service by 29%.
- Prompt Injection Resistance: Achieves a 0.0% compromise rate on the Gray Swan IPI Benchmark, blocking the risk of hackers inserting malicious code into input data to take control.
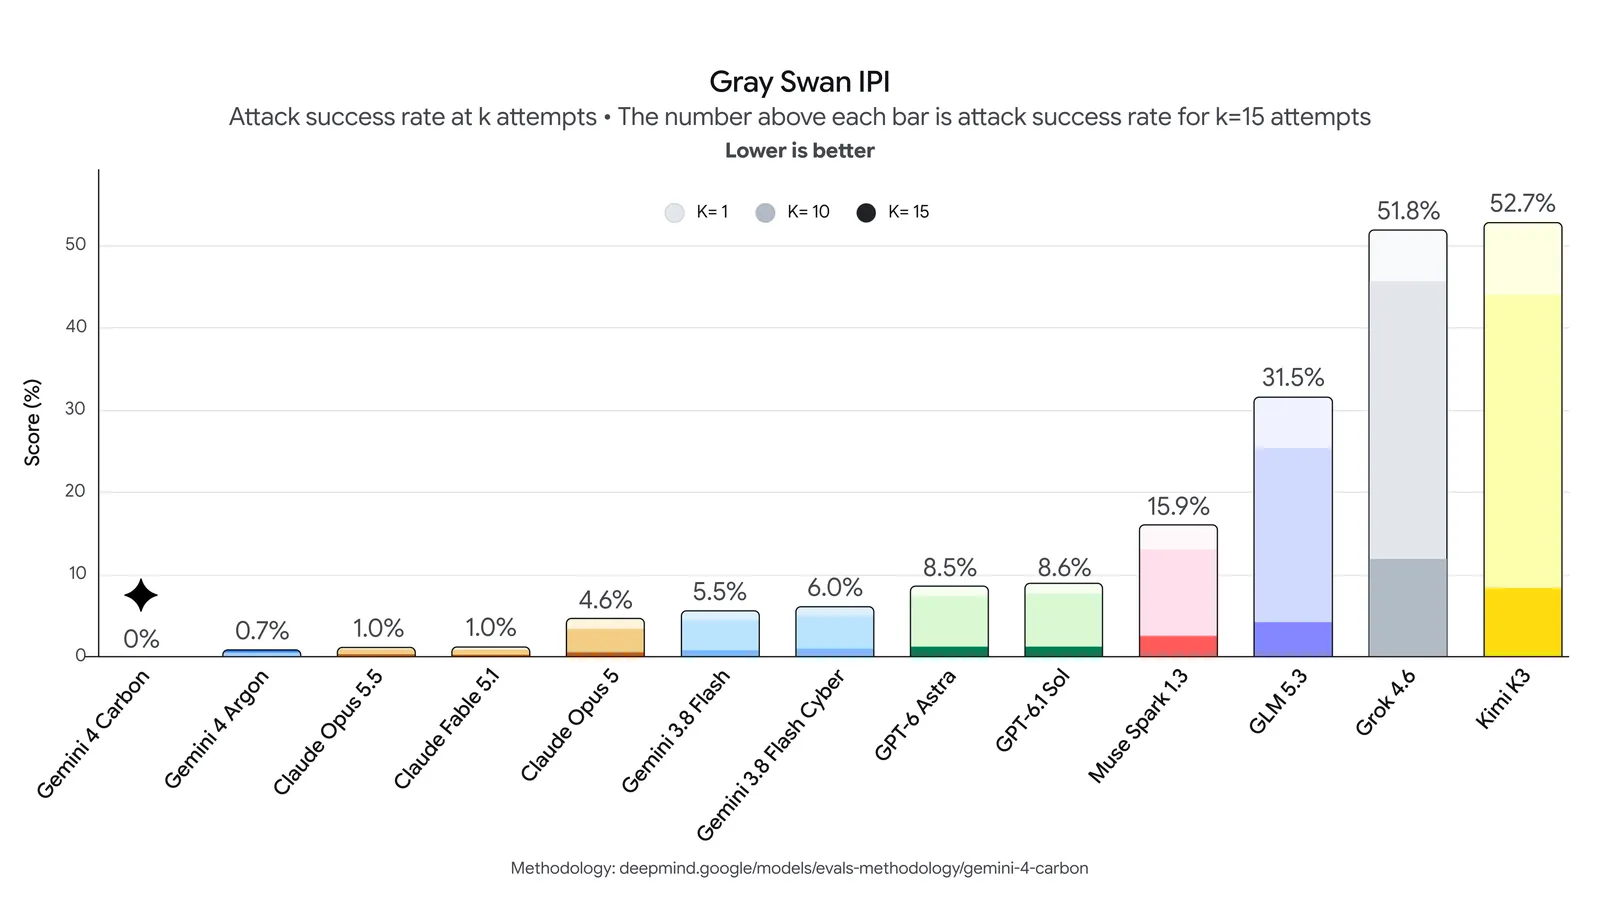
Resistance to Indirect Prompt Injection attacks on Gray Swan IPI achieves a 0.0% breach rate (Source: Google DeepMind).
6. API Costs and Practical Applications at DPS.MEDIA
Google has kept Gemini 4 Carbon's starting price on par with the Argon version:
- Input Tokens: USD 2 per 1 million tokens.
- Output Tokens: USD 10 per 1 million tokens.
- Cached Input Tokens: Up to 95% off, costing just USD 0.10 per 1 million tokens.
The price of USD 0.10 per 1 million cached tokens is a key factor in enabling n8n automation workflows and long-running agents to operate at optimized costs.
At DPS.MEDIA, we believe this model delivers two core benefits:
Enhanced Security for WordPress Systems: Automate plugin source-code audits, check REST API access permissions, and prevent data vulnerabilities before delivering projects to clients.
Expand Secure Agentic Workflows: Integrate AI confidently into chatbot scenarios, lead processing, and multichannel data extraction without worrying about prompt injection risks from unknown users.
7. How Should Businesses Prepare for the Agentic AI Era?
To fully leverage the power of autonomous AI, businesses should follow three principles:
- Standardize Source Code Structure: Create clear technical documentation and consistent naming conventions so agents can easily understand the context.
- Deploy a Sandbox Environment: Isolate AI testing environments from production systems and implement automated testing procedures.
- Maintain Human-in-the-Loop Approval: Critical changes to live systems must always be confirmed by the responsible engineer.
If your business needs to build secure, SEO-compliant websites, develop n8n automation workflows, or apply AI to business operations, DPS.MEDIA is ready to work alongside you to turn your growth goals into reality.
DPS.MEDIA JOINT STOCK COMPANY
📍 Address: 56 Nguyen Dinh Chieu, Tan Dinh Ward, Ho Chi Minh City
📞 Hotline / Zalo: 0961 545 445
✉ Email: marketing@dps.media
🌐 Website: https://dps.media
🏢 Tax identification number: 0318700500 | VCB: 1051160909
Ý kiến bạn đọc (9)
Đăng nhập để bình luận
Đăng nhập nhanh 1-chạm bằng Google để chia sẻ ý kiến của bạn về bài viết.
Bằng cách đăng nhập, bạn đồng ý với điều khoản và chính sách cộng đồng.
Chưa có bình luận nào. Hãy là người đầu tiên chia sẻ cảm nghĩ!
Đăng nhập / Tạo tài khoản
Đăng nhập với Google để gửi bình luận và tương tác cùng cộng đồng.
Tiếp tục là đồng ý với điều khoản sử dụng và chính sách bảo mật của DPS Media.